SRE Meaning: What Is Site Reliability Engineering (SRE) and What Does an SRE Do?
Quick answer
SRE stands for Site Reliability Engineering, a way of running production systems that treats operations as a software problem. Engineers write code and automation to keep applications reliable, and use measurable targets, SLOs and error budgets, to decide how fast a team can safely release changes. A Site Reliability Engineer, also called an SRE, is the person who does this work.
SRE stands for Site Reliability Engineering. It is a way of running production systems where you treat operations as a software problem: engineers write code and automation to keep applications reliable, and they use measurable targets (SLOs and error budgets) to decide how fast the team can safely release changes. A Site Reliability Engineer (also called an SRE) is the person who does this work.
In this article I explain both, step by step: where SRE came from, how SLOs and error budgets work in practice, what an SRE does day to day, and how SRE compares to DevOps.
This is the written version of my YouTube video on SRE. If you prefer watching, you can find the full explanation there.
If you are new to DevOps, I recommend reading my What is DevOps article first. It will make this one much easier to follow.
What does SRE mean in tech?
In technology, SRE means Site Reliability Engineering, a discipline that applies software engineering to IT operations so that systems stay available, fast and correct while the product keeps changing. The same three letters also describe the job title Site Reliability Engineer.
So “SRE meaning in IT”, “SRE meaning in DevOps” and “SRE meaning in software” all point to the same idea. The word “site” is a bit historical: it comes from running websites at Google, but today SRE applies to any production system, like APIs, mobile backends, data platforms or internal tools.
Here is the short version you can remember:
| Term | What it means |
|---|---|
| SRE (the practice) | Site Reliability Engineering: keeping production systems reliable using software, automation and measurable targets |
| SRE (the role) | Site Reliability Engineer: the engineer responsible for reliability, monitoring, incident response and automation |
| Reliability | The system does what users expect, when they need it: it is available, fast enough and returns correct results |
| SLO | Service Level Objective: an internal reliability target, for example 99.9% of requests succeed |
| Error budget | The amount of unreliability you are allowed, for example 0.1% of requests may fail |
Where did SRE come from, and why was it needed?
SRE was created at Google in the early 2000s, when Ben Treynor Sloss (you will often see his name searched as “Ben Traynor”) was asked to run a small team of software engineers doing what used to be operations work. His well-known description of it is that SRE is “what happens when you ask a software engineer to design an operations team.”
To understand why that was needed, look at how software used to be delivered. In a traditional setup, developers and operations were two separate teams with opposite goals:
- Developers want to push application changes to users as fast as possible
- Operations want to keep the application stable, so they are careful about every single change
This creates a conflict of interest. The two roles end up working against each other instead of together:
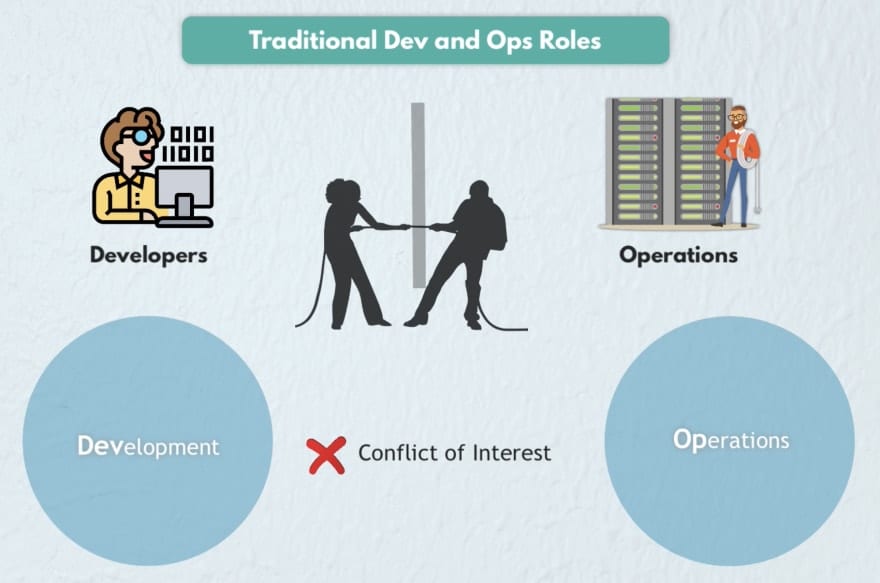
DevOps was introduced to fix exactly this problem, and it made releases much faster. But in practice, faster releases were not always stable releases, and there was often nobody whose full-time job was keeping production reliable. That gap is why SRE, and the Site Reliability Engineer as a separate role, became so popular.
What is system reliability, and why does it matter?
A system is reliable when users can depend on it: it is up when they need it, it responds fast enough, and it gives correct results. “System” here means the whole deployment environment where the application runs: the servers, infrastructure and platform, not just the code.
Think about it from the user side. If your email provider was down once a week, you simply could not rely on it. And the interesting thing is that users do not notice reliability at all. It only becomes visible when something goes wrong: big outages at social networks or cloud providers make the news, and a cloud outage can take down every application hosted there.
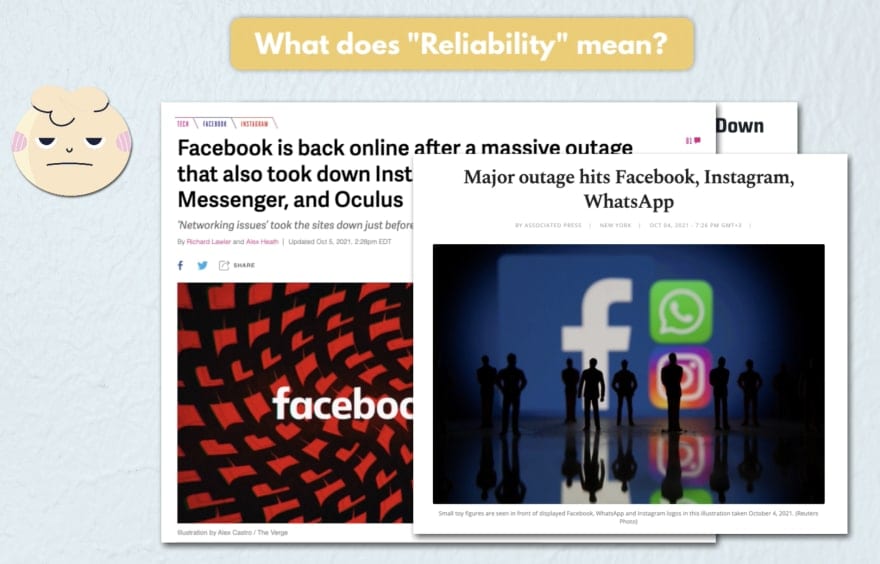
And the impact of unreliable systems is very concrete: unhappy customers and lost revenue. Imagine an online shop going down during a holiday sale. Nobody can order anything, so that business is simply lost.
How does SRE make systems reliable?
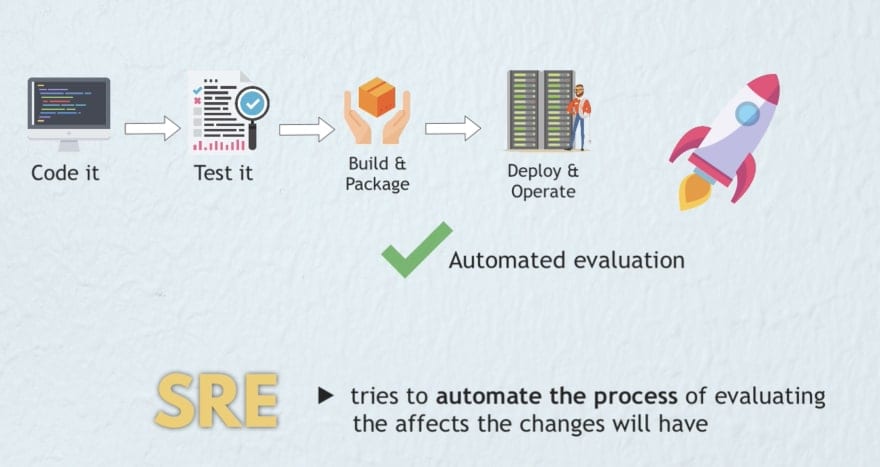
SRE makes systems reliable by measuring reliability with numbers and automating the decision of whether a change is safe to release, instead of relying on manual checklists and long approval meetings.
Here is the background. The main reason systems become unreliable is change: a change in the infrastructure, the platform, the application or one of its services. Any change can break something.
One “solution” would be to allow fewer changes, but that hurts the business, because you need new features to stay competitive. So traditionally, developers made a change and operations evaluated it with long checklists, which slowed down every release:
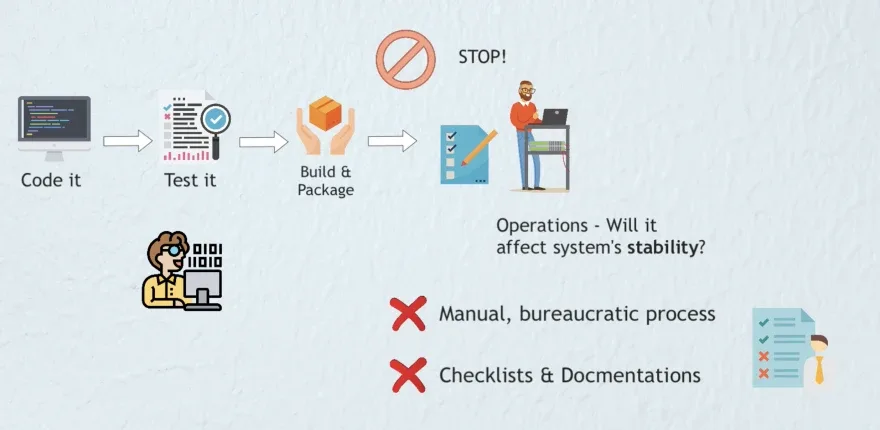
SRE’s answer is to automate the evaluation. Instead of discussions about whether to release, the decision is based on data: is the service currently within its reliability target or not? That makes releasing changes fast and safe at the same time.
What are SLA, SLO and SLI in SRE?
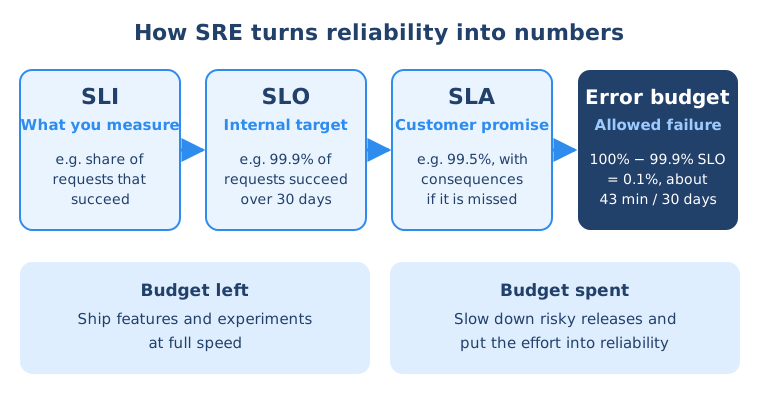
An SLI (Service Level Indicator) is what you measure, an SLO (Service Level Objective) is the target you set for that measurement, and an SLA (Service Level Agreement) is the promise you make to customers, usually with consequences if it is broken. In SRE work, the SLO is the number engineers use day to day.
A simple example for an online shop:
- SLI: the percentage of checkout requests that succeed in under 500 ms
- SLO: 99.9% of checkout requests meet that bar over a rolling 30 days
- SLA: the contract with business customers promises 99.5%, with service credits if it is missed
The SLA is usually a bit looser than the SLO, so the team gets a warning before it breaks a promise to customers.
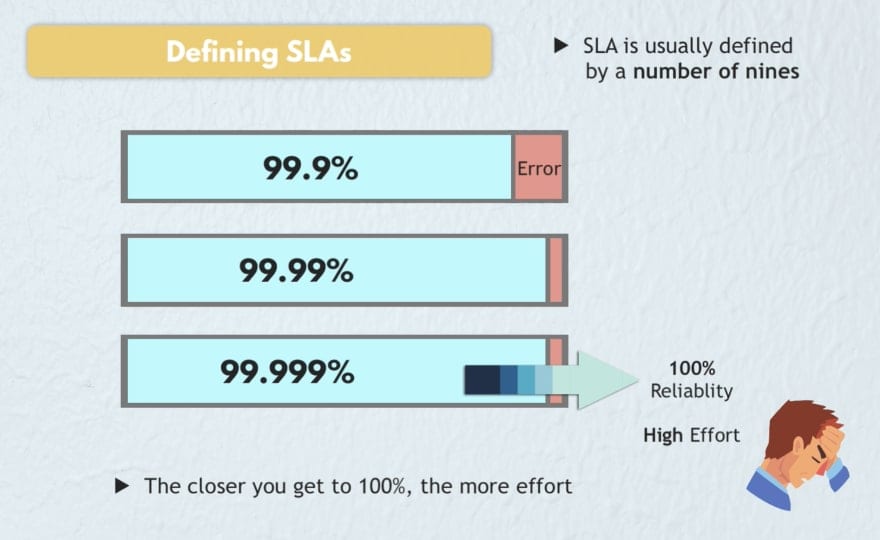
Reliability targets are often described by their “number of nines”. Here is how much downtime per year each level allows:
| Availability target | “Nines” | Allowed downtime per year |
|---|---|---|
| 99% | two nines | about 3.65 days |
| 99.9% | three nines | about 8.8 hours |
| 99.99% | four nines | about 53 minutes |
| 99.999% | five nines | about 5 minutes |
And availability is not the only thing you can define targets for. Common SLIs also include response time (latency) and error rate. For example, if your application serves a million requests a week with a 99% target, at least 990,000 of those requests need to succeed.
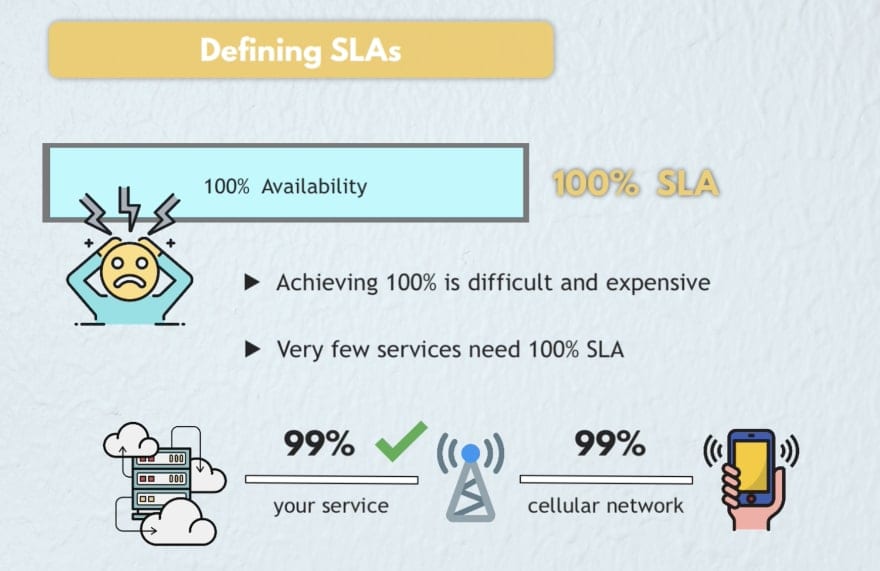
Why not aim for 100% reliability?
Because 100% is extremely hard to achieve, and most services do not need it. If your users’ internet connection or their phone is not 100% reliable, your service effectively cannot be more reliable than that anyway. The closer you get to 100%, the more effort each extra nine costs.
Who defines these targets?
Business people and engineers define them together. The business side brings industry benchmarks, competition and user feedback and decides on a high level how reliable the product must be. SREs and DevOps engineers then turn that into technical SLIs and SLOs and build them into their monitoring, alerting and release processes.
What is an error budget?
An error budget is the amount of unreliability your SLO allows: 100% minus your SLO. With a 99.9% availability SLO over 30 days, your error budget is 0.1%, which is about 43 minutes of downtime (or 0.1% of failed requests) in that period.
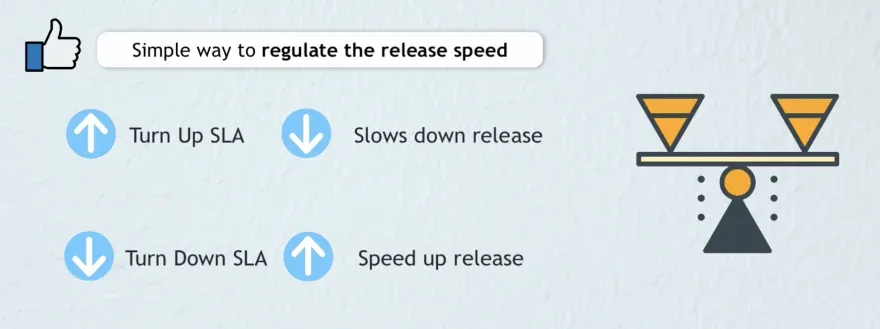
The clever part is how SRE uses it. The team is allowed to “spend” that budget on risky changes, experiments and new features. So the error budget works like a regulator for release speed:
- Budget left: the system is more reliable than the target, so developers can release more changes, faster
- Budget spent: the system has been less reliable than the target, so risky releases slow down and the team puts its effort into reliability until the service is back within its SLO
This takes the emotion out of the old developers-vs-operations argument. Nobody has to win a discussion. The number decides, and both sides want the same thing: stay within the target while shipping as much as possible.
Want to see where SRE skills fit in a DevOps career?
Monitoring, automation, Kubernetes and cloud are the foundation of SRE work. My free DevOps Roadmap shows you which skills to learn and in which order.
What does an SRE do?
A Site Reliability Engineer keeps production systems reliable by automating operations work, setting up monitoring and alerting, responding to incidents and fixing the root causes so the same problems do not happen again. Here are the main tasks and responsibilities.
1. Automate operational work
SREs build automated processes that calculate whether a service is within its SLO and that feed that information into the release process. So instead of an endless operations checklist, the release policy is automated. SREs also automate repetitive manual work (Google calls this “toil”), like restarting services, scaling or rotating certificates.
2. Set up monitoring and observability
You cannot measure reliability without visibility. A big part of the job is configuring monitoring, logging and tracing so the team can see what is happening inside the system and measure it against the SLOs. Tools like Prometheus and Grafana are very common here. I show a practical setup in How to set up Prometheus monitoring in Kubernetes.
3. Detect issues early with good alerting
Since the target is not 100%, outages will happen at some point. Monitoring and alerting help you detect signs of a problem early and notify the right people.
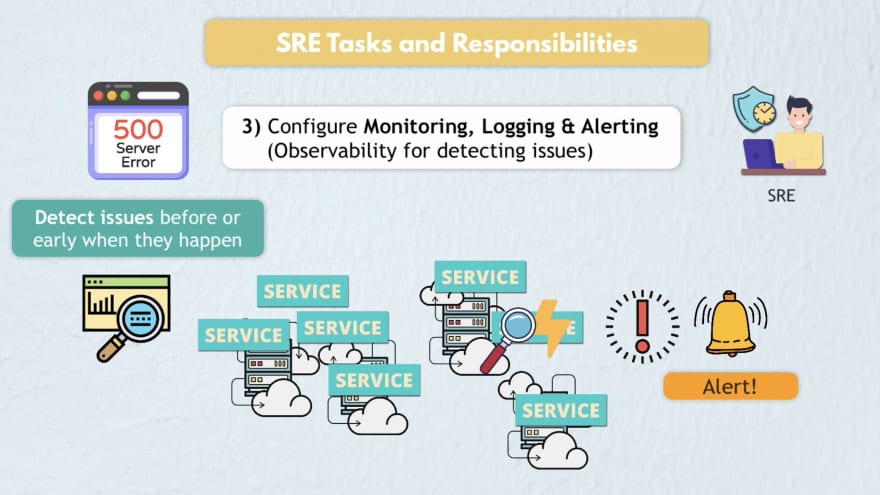
A good alert contains everything needed to fix the problem fast. Instead of “something is wrong in the cluster”, it says “service A in cluster B is returning 500 errors”. Now you know which service, where, and what the problem is. SREs often write their own tooling to get alerts and logs to that level.
4. Be on call and respond to incidents
When things break and users need help in real time, someone is on call. Putting SREs on the on-call rotation means they see firsthand which issues happen, how support deals with them, and what could be improved. For example: did the alert contain enough information? Was the issue detected too late?
The goal is to keep the scope of every outage small: it is fixed quickly, and as few users and services as possible are affected.
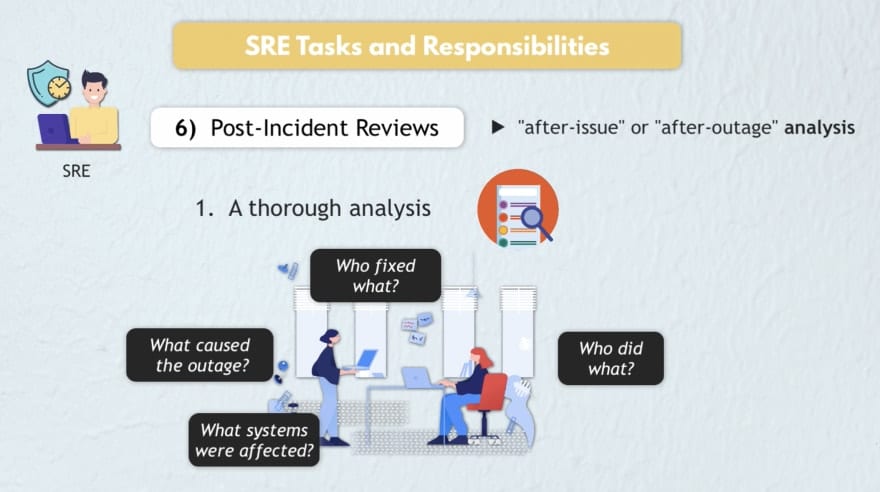
5. Run blameless post-incident reviews
Fixing the outage is not the end. SRE teams write a postmortem: a thorough analysis of what happened, why, and what will prevent it next time. The key rule is to stay blameless, so people feel safe admitting mistakes and everyone learns from them. And everything gets documented for future reference.
Who does SRE work? The SRE role in a team
In many companies SRE is its own role, with dedicated engineers whose full-time job is keeping systems reliable. In others, developers and SREs sit in one team and share the responsibility.
Why a separate role? Because it would be a lot to ask developers to learn all the operations tools on top of everything they already need to know. So you often have SRE teams that are effectively the new operations team, working toward the same SLOs as the developers:
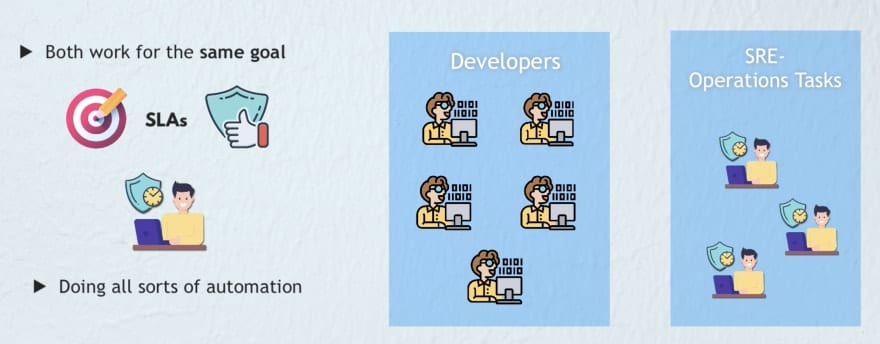
In both setups, SREs need solid coding skills (often Python or Go), plus Linux, networking, cloud platforms, Kubernetes, infrastructure as code, and monitoring tools. The big change compared to the traditional model is that dev and ops now have the same incentives and sit on the same side.
What is the difference between SRE and DevOps?
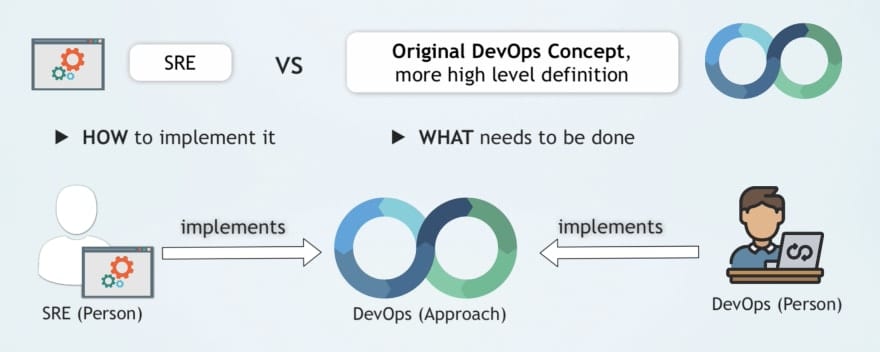
DevOps is a broad culture and set of practices for delivering software quickly and safely, while SRE is a more specific, engineering-driven way to implement those ideas with a strong focus on reliability. Many people describe it as “SRE implements DevOps”, and Google itself puts it in similar terms.
If you watched my “What is DevOps” video, you know there are two ways to define DevOps: the original, high-level concept, and the practical DevOps engineer role that evolved over time. So the comparison depends on which one you mean.
Compared to DevOps as a concept: DevOps defines what needs to happen (an automated, streamlined release process with shared responsibility). SRE is more specific about how to do it, with SLOs, error budgets and automation.
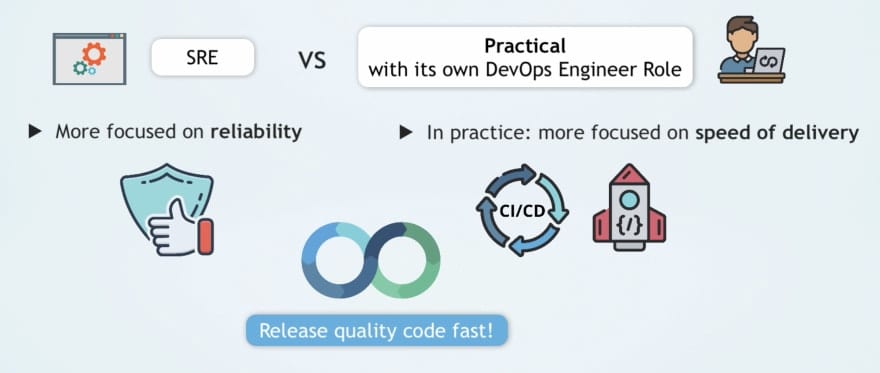
Compared to the DevOps engineer role: in practice, many DevOps teams focus mostly on the speed of delivery, like CI/CD pipelines and infrastructure automation. SRE shares the same goal of releasing quality code fast, but it is focused on keeping production stable while changes keep flowing.
| DevOps engineer | Site Reliability Engineer (SRE) | |
|---|---|---|
| Main focus | Speed and automation of delivery | Reliability of production systems |
| Typical work | CI/CD pipelines, infrastructure as code, containers, cloud setup | SLOs and error budgets, monitoring and alerting, on-call, incident response, postmortems |
| Key question | “How do we ship changes faster and more safely?” | “How reliable must this be, and are we within that target?” |
| Coding | Mostly scripting and automation | Often more software engineering, building internal reliability tools |
| Shared ground | Linux, cloud, Kubernetes, IaC, monitoring, automation | Same |
So they are two sides of the same coin, and many companies have both roles working together. The tool stack overlaps a lot, which is why people often move from DevOps into SRE or the other way around.
Frequently asked questions
What does SRE stand for?
SRE stands for Site Reliability Engineering. It is also used for the job title Site Reliability Engineer. Both refer to keeping production software systems reliable by applying software engineering, automation and measurable reliability targets to operations work.
What does an SRE do day to day?
A Site Reliability Engineer sets up monitoring and alerting, defines and tracks SLOs and error budgets, automates repetitive operations work, takes part in on-call rotations, and leads blameless postmortems after incidents. They also work with developers on performance, capacity and resilience so that new releases do not hurt reliability.
Is SRE the same as DevOps?
No, but they are closely related. DevOps is a broad culture and set of practices for delivering software fast and safely, while SRE is a specific engineering approach to implementing those ideas with a strong focus on reliability. Many companies have both roles, and their skills overlap a lot.
Who created SRE?
SRE was created at Google in the early 2000s by Ben Treynor Sloss, who was asked to run a team of software engineers doing operations work. Google later published its practices in the books “Site Reliability Engineering” and “The Site Reliability Workbook”, which are available to read for free online.
What is the difference between SLA, SLO and SLI?
An SLI is the metric you measure, like the percentage of successful requests. An SLO is your internal target for that metric, like 99.9% over 30 days. An SLA is the external promise to customers, often with financial consequences if it is broken, so it is usually set a bit lower than the SLO.
What skills do you need to become an SRE?
You need a good foundation in Linux, networking and at least one programming language such as Python or Go. On top of that come cloud platforms, containers and Kubernetes, infrastructure as code, CI/CD, and monitoring tools like Prometheus and Grafana. Many SREs start as software developers, system administrators or DevOps engineers.
Where to go from here
Learn the skills behind DevOps and SRE work, hands-on
In the DevOps Bootcamp you learn Linux, cloud, containers, Kubernetes, infrastructure as code, CI/CD and monitoring by building real projects step by step, the same foundation SRE work is built on.
You can find more DevOps and SRE content on my YouTube channel, and you can follow me on LinkedIn and Instagram for regular updates.